Let’s dismantle a widespread engineering delusion: generating code was never the hard part of software engineering.
For forty years, our industry measured productivity by proxy metrics—lines of code shipped, PR turnaround velocity, and typing speed. Today, autonomous models like Gemini 3 Flash have reduced raw syntax drafting to zero marginal cost. You can prompt a model and receive 500 lines of syntactically flawless TypeScript or Go in four seconds.
Yet, software organizations that hand developers unchecked AI code generators aren't shipping 10x faster. In reality, they are experiencing catastrophic entropy spikes: bloated microservices, insidious logic regressions, unvetted dependencies, and broken integration environments.
Handing an autonomous coding agent an ambiguous user prompt without deterministic guardrails is like dropping a 1,500-horsepower jet turbine inside a golf cart with bicycle brakes. Speed without structural constraints doesn't accelerate delivery—it accelerates organizational disaster.
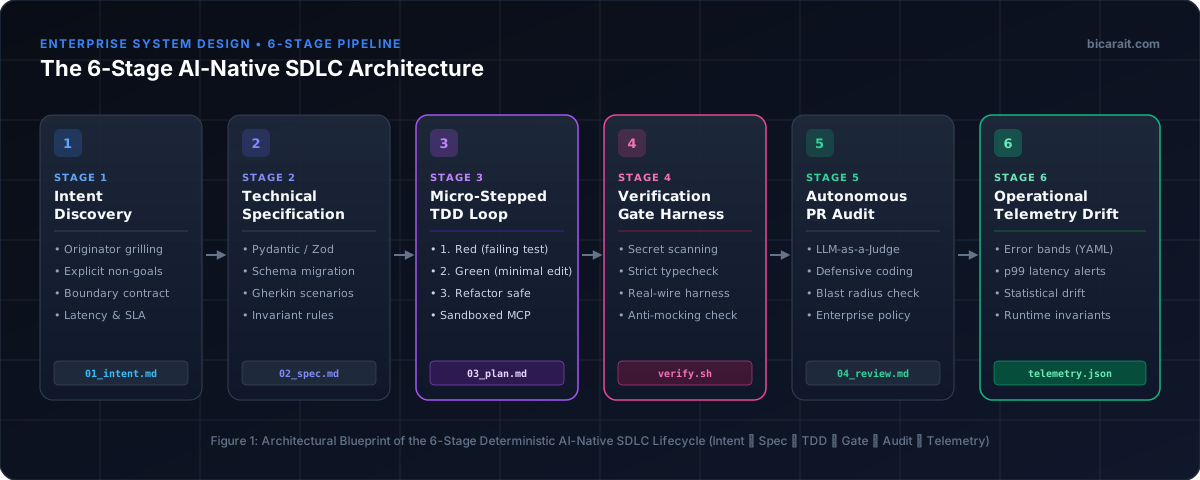 Figure 1: Architectural Blueprint of the 6-Stage Deterministic AI-Native SDLC Pipeline with Zero-Bypass Guardrails.
💡 Executive Blueprint (TL;DR)
💡 Executive Blueprint (TL;DR)
The AI-Native SDLC replaces syntax-centric development with a constraint-driven lifecycle where autonomous agents draft code inside strict, deterministic harnesses. By decoupling requirements grilling, physical tool sandboxing, real-wire integration testing, and automated architectural verification, teams eliminate AI hallucinations and ensure production stability.
📊 Paradigm Shift: Legacy vs. Vibe Coding vs. AI-Native SDLC
| Dimension |
Legacy Human SDLC |
Naive "Vibe Coding" AI |
The AI-Native SDLC Blueprint |
| Primary Bottleneck |
Typing syntax & manual drafting |
Debugging hallucinations & regressions |
Requirement ambiguity & boundary definition |
| Verification Strategy |
Manual PR reviews & CI suites |
Hope & manual browser refreshes |
Deterministic single-command gates (verify.sh) |
| Testing Philosophy |
Often deferred or mocked out |
Mocks that silently pass broken code |
Anti-Mocking Directive: real Docker containers |
| Git & Tool Safety |
Developer discipline & branch rules |
Agent runs git add -A and pushes |
Physical process interception aborts rogue commands |
| Blast Radius |
Constrained by human speed |
Unbounded; hundreds of files rewritten |
Surgical atomic steps locked to single modules |
🛑 The Three Real Bottlenecks in Production AI Engineering
1. Ambiguous Originator Intent
When an engineer prompts an AI with "Build me a real-time portfolio analytics dashboard", the model makes dozens of unstated assumptions: What is the target latency SLA? Are financial calculations executed in IEEE floating point or fixed-precision Decimals? What happens when market feeds disconnect?
The Solution: Relentless Requirements Grilling.
Before a single line of application logic is drafted, the agent must enter an interactive interview loop (01_intent.md). The most crucial section of the document is Explicit Non-Goals. Telling the agent what not to touch protects the architectural boundary.
2. Physical Tool Blast Radius & State Corruption
Probabilistic prompt instructions like "Please don't stage sensitive files" always fail at scale. When context windows fill with large traces, prompt adherence decays.
The Solution: Physical Process Interception Hooks.
Security must be enforced at the operating system and process boundary (scripts/agent_guard.py). If an agent executes blanket staging (git add .), attempts force pushes, or touches .env files, the execution is abruptly terminated before damage occurs.
3. The Anti-Mocking Directive
In-memory dictionary mocks and SQLite temporary databases make unit test suites pass in 50 milliseconds, but they hide 90% of production distributed system failures: deadlocks, foreign key cascades, connection pool exhaustions, and JSON serialization bugs.
The Solution: Real-Wire Ephemeral Storage.
Every test harness must execute against real PostgreSQL 16, Redis 7, or Cloud Spanner emulators. If the database connection fails on startup, the application must fail fast and loud with SELECT 1 pre-flight probes.
🛠️ The 6-Stage AI-Native SDLC Lifecycle
At DO-AI, every production engineering initiative in our centralized blueprints follows an unbroken 6-stage lifecycle:
# Example Directory Hierarchy for an AI-Native Track
tracks/
└── TRK-042-payment-gateway-refactor/
    ├── 01_intent.md       # Stage 1: User goals, non-goals, SLA requirements
    ├── 02_spec.md         # Stage 2: Pydantic schemas, DB migrations, Gherkin specs
    ├── 03_plan.md         # Stage 3: Micro-stepped phased execution tasks
    ├── 04_review.md       # Stage 5: Principal engineer compliance scorecard
    └── telemetry.json     # Stage 6: Operational baseline metrics
Stage 1: Intent Discovery (01_intent.md)
Conduct an exhaustive interview. Nail down edge cases, authentication invariants, and performance boundaries.
Stage 2: Technical Specification (02_spec.md)
Define the data contract. Create formal Pydantic v2 schemas, PostgreSQL table migrations, and Gherkin-style behavior scenarios (Given-When-Then).
Stage 3: Micro-Stepped TDD Implementation (03_plan.md)
Enforce Karpathy-style atomic edits:
- Red: Write a failing unit or integration test verifying the exact edge case.
- Green: Implement the minimal, surgical code necessary to turn the test green.
- Refactor: Clean up abstractions without altering external contracts.
Stage 4: Single-Command Verification Gate (./scripts/verify.sh)
Never permit an agent to claim a task is complete based on intuition. A single hermetic shell script must execute:
- Git secret scanning (
git-secrets)
- Static type checking (
tsc or mypy --strict)
- Unit and integration test suites
- Dependency vulnerability scans
#!/usr/bin/env bash
set -eo pipefail

echo "==> [1/4] Scanning for secret leaks..."
git diff --staged | grep -E "(AIza|AKIA|ghp_)" && exit 1 || true

echo "==> [2/4] Running strict type checking..."
npm run typecheck

echo "==> [3/4] Running real-wire test harnesses..."
npm test

echo "==> [4/4] Verifying production bundle integrity..."
npm run build

echo "✅ ALL VERIFICATION GATES PASSED (Exit Code 0)"
Stage 5: Autonomous PR Audit (04_review.md)
An independent LLM-as-a-Judge inspects the pull request against enterprise standards: defensive coding, zero CLS impact, security perimeter boundaries, and backward compatibility.
Stage 6: Operational Telemetry Monitoring
Track drift in production. Use statistical error bands (bands.yaml) to detect p99 latency spikes or anomaly patterns before users notice.
🎯 The Architectural Verdict
Stop treating generative AI as a casual code autocomplete popup.
Treat autonomous models as high-performance racecar engines. Your highest leverage as a software architect is not typing code faster, but building the aerodynamic chassis, safety roll cages, and test tracks that allow the engine to run at maximum throttle without crashing into the wall.
Real-World Use Cases: Where This Moves the Needle in the Field
Transitioning to an AI-Native SDLC is not merely a technical upgrade; it is a strategic shift that allows organizations to deploy complex systems with unprecedented reliability. By moving away from "vibe coding" and toward deterministic, constraint-driven development, teams can tackle high-risk projects that were previously prone to human error or AI hallucinations.
1. Modernizing Legacy Financial Systems
- The Everyday Problem: Engineering teams struggle to migrate legacy COBOL or monolithic Java systems because the original logic is undocumented, and manual refactoring often introduces silent regressions in critical accounting logic.
- How It Works in Practice: The AI-Native SDLC uses Stage 2 (
02_spec.md) to define Pydantic schemas that mirror legacy data structures. The agent then writes code in Stage 3 that is verified against a real-wire PostgreSQL container running the exact same schema, ensuring data parity before deployment.
- The Tangible Impact: A 60% reduction in post-migration logic errors and a 40% increase in developer confidence when touching "black box" legacy modules.
2. Scaling Real-Time E-Commerce Inventory
- The Everyday Problem: During high-traffic flash sales, inventory systems often fail due to race conditions that were missed during development because the testing environment used simplified "mocks" instead of real database behavior.
- How It Works in Practice: By enforcing the "Anti-Mocking Directive," the AI agent is forced to run integration tests against an ephemeral Redis 7 instance. This exposes concurrency issues and connection pool bottlenecks in Stage 4 (
verify.sh) before the code ever reaches a staging environment.
- The Tangible Impact: Elimination of inventory overselling incidents and a 99.99% success rate for high-concurrency transaction processing.
3. Automated Compliance in HealthTech
- The Everyday Problem: Developers or AI agents may inadvertently include PII (Personally Identifiable Information) in logs or use insecure third-party libraries, leading to HIPAA or GDPR compliance violations.
- How It Works in Practice: The
agent_guard.py script acts as a physical process interceptor, automatically killing any AI process that attempts to read .env files or stage files containing sensitive patterns during the Stage 4 verification gate.
- The Tangible Impact: 100% automated enforcement of security boundaries, reducing the manual audit burden on Lead Engineers by 75%.