News Flash: Why is Speculative Decoding Fast, ATLAS: Evaluating Agents, & Quicksand?
1. The Mechanics of Speculative Decoding: Shifting from Memory to Compute
The News Highlight:
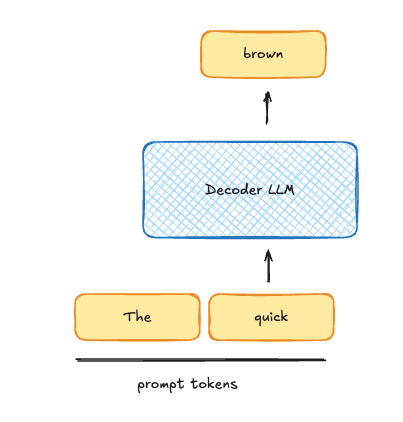
Speculative decoding is often misunderstood as a method to reduce the total workload of a Large Language Model (LLM). In reality, it increases the total number of floating-point operations (FLOPs) executed for a given sequence. The speedup occurs because LLM inference is typically memory-bound; the GPU spends more time moving model parameters from global memory to local registers than it does performing actual calculations. Speculative decoding leverages a smaller "draft" model to predict a sequence of tokens, which the larger "target" model then verifies in a single parallel forward pass. This utilizes "free" compute cycles that would otherwise be wasted while the GPU waits for memory transfers, effectively turning a memory-bound process into a compute-bound one.
- Draft-Verify Architecture: A small, fast model proposes $N$ tokens; the large model validates them all at once, accepting the prefix that matches its own distribution.
- Memory vs. Compute Bound: Traditional auto-regressive decoding streams all model parameters (e.g., 27B for Qwen 3.5) for every single token; speculative decoding streams them once for multiple tokens.
- Efficiency Thresholds: The technique is highly effective when batch sizes are small and compute resources are underutilized, but it can become a bottleneck at very high throughput where memory bandwidth is already saturated.
- Hardware Utilization: It optimizes the "Roofline Model" of GPU performance by increasing the operational intensity of the inference task.
DO-AI Analysis:
From a first-principles architectural perspective, speculative decoding is a latency optimization trick that trades FLOP efficiency for time efficiency. For enterprise engineering teams, the takeaway is clear: this is not a "free lunch" for throughput. If your inference server is already running at maximum batch capacity (compute-bound), adding a draft model will likely degrade performance due to the overhead of running two models. However, for user-facing applications requiring low-latency single-stream responses, speculative decoding is the premier architectural pattern to mask the I/O bottleneck of massive parameter weights.
2. ATLAS: A New Frontier for Evaluating Search-Intensive AI Agents
The News Highlight:
Exa has introduced ATLAS, a rigorous new benchmark designed to evaluate the performance of AI agents on complex, search-heavy tasks that reflect real-world research workflows. Unlike traditional benchmarks that often rely on memorized facts within a model's training data, ATLAS focuses on "unmemorized" tasks requiring multi-step web discovery and data synthesis. The benchmark reveals a significant performance gap in the current agent landscape: even high-compute, "max-effort" agents fail to capture approximately one-third of the required "golden" answers. The results underscore that achieving high accuracy and completeness in agentic search remains an expensive and unsolved challenge.
- Multi-Metric Grading: Uses "Discovery F1" (entity finding), "Row F1" (complete record accuracy), and "Item F1" (individual cell accuracy) to provide a granular view of agent performance.
- Economic Benchmarking: Findings show that no agent costing less than $1.00 per task achieved a "Row F1" score higher than 0.5, highlighting a steep cost-to-quality curve.
- Dynamic Pipeline: Features an automated pipeline to refresh queries and ground-truth answers, preventing data leakage and ensuring the benchmark evolves alongside the live web.
- Search Depth: Requires agents to perform wide and deep searches across multiple domains, moving beyond simple single-query Retrieval-Augmented Generation (RAG).
DO-AI Analysis:
ATLAS represents a shift in AI evaluation from "what the model knows" to "how well the agent works." For architects building production-grade RAG or research agents, the ATLAS data is a sobering reminder that "naive RAG" is insufficient for complex data extraction. The primary bottleneck identified isn't just the LLM's reasoning, but the search engine's ability to surface deep, non-obvious results. Engineering teams should prioritize "agentic search" architectures—where the agent iteratively refines its search queries—rather than relying on a single retrieval step, while carefully monitoring the escalating token costs associated with high-recall tasks.
3. Quicksand: Microsoft’s New Sandbox for Secure Agent Execution
The News Highlight:
Microsoft has released Quicksand, an asynchronous Python API designed to manage QEMU virtual machines specifically for sandboxing AI agents. As agents are increasingly tasked with generating and executing code, the need for secure, isolated environments has become critical. Quicksand provides a lightweight way to launch, control, and snapshot VMs without requiring root privileges or Docker. It supports both x86_64 and ARM64 architectures across Windows, macOS, and Linux, offering pre-built Ubuntu and Alpine Linux images. This allows developers to give AI agents a "playground" where they can install packages and run scripts without risking the host system's integrity.
- Rootless Operation: Runs entirely in user space using QEMU, eliminating the security risks associated with granting agents access to a Docker socket or root permissions.
- State Management: Supports VM snapshotting, allowing developers to save the state of a sandbox and revert to it if an agent's actions lead to an error or security breach.
- Granular Isolation: Features default network isolation with optional opt-in for specific ports, and supports mounting host directories for controlled data exchange.
- Multi-Agent Support: Allows for the creation of multiple independent Linux user accounts within a single VM, enabling multi-agent collaboration in a shared but controlled environment.
DO-AI Analysis:
Quicksand addresses the "execution gap" in agentic workflows. While Docker has been the industry standard for containerization, it was never designed as a security boundary for untrusted code execution by autonomous agents. By utilizing QEMU-based virtualization, Quicksand provides a much stronger isolation layer (hardware-level virtualization) which is essential for enterprise deployments where agents might interact with sensitive data or external APIs. The ability to snapshot and revert VM states is a game-changer for debugging non-deterministic agent behavior and ensuring reproducible execution environments.
Morning Executive Comparison Matrix
| Dispatch |
Core Domain |
Production Maturity |
DO-AI Recommendation |
| Speculative Decoding |
Inference Optimization |
High (Deployment) |
Implement for low-concurrency, latency-sensitive LLM applications. |
| ATLAS Benchmark |
Agent Evaluation |
Emerging (R&D) |
Use to baseline the accuracy of multi-step research and discovery agents. |
| Quicksand |
Agent Security |
Beta (Tooling) |
Adopt for secure, rootless execution of agent-generated code in production. |