
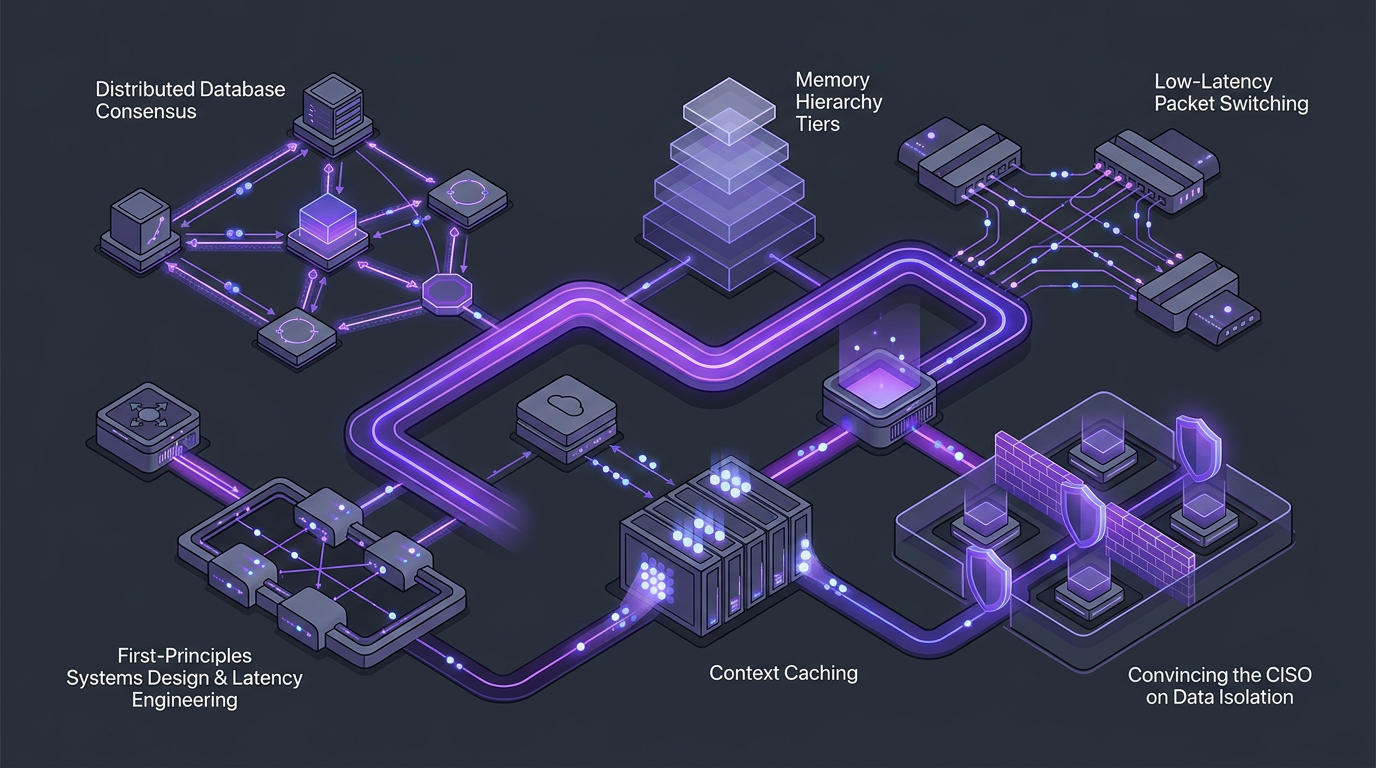
Architecture Masterclass: High-Throughput KV-Cache & Token Economics
The Cost Trap: Why Enterprise LLM Stacks Bleed Money
When scaling generative AI into production, unoptimized context windows and re-computed prompt prefixes create an exponential cost curve.